A bug report is a record of something a product did that it should not have done, written so someone else can reproduce it. That second clause is the whole difficulty. A report that proves a problem exists but does not let a developer see it happen again is a complaint with a ticket number.
One disambiguation before anything else, because it trips people up: on Android, “bug report” also means a diagnostic dump captured from the device — a technical artifact about system state, not something a person composed. If that is what you came for, this is the wrong page. Everything below is about the report a human writes.
What are bug reports for?
Two jobs, and they are not equally hard.
Proving the problem exists is easy. A screenshot does it, and most reports manage it.
Making it reproducible is the job that fails. A developer needs to reach the same broken state on their own machine, and the report has to carry enough for that: which build, which device, which sequence of actions, and what was expected instead. The reporter knows all four at the moment they file. A week later nobody does.
This is why the bug report meaning matters more than the format. It is not documentation of an event. It is a set of instructions for recreating one.
The anatomy
Title
What breaks and where, specifically enough to distinguish it from a similar bug.
Environment
Device, operating system, browser or app version. "On mobile" is not an environment.
Build
The exact version. Without it nobody can tell whether it is already fixed.
Steps to reproduce
Numbered, from a known starting state, including the data used.
Expected result
What should have happened. Skipping it is how "working as designed" arguments start.
Actual result
What happened instead, with error text quoted exactly rather than paraphrased.
Evidence
A screenshot at minimum. The field reporters fill in most willingly.
In a tracker these become fields. Jira represents each report as a work item carrying core fields — Project, Key, Summary, Type, Status, Priority and Resolution — where the Description field supports long text with code blocks, tables and images. Note that the field long labelled Summary has been renamed Title in the current Jira Cloud interface, though queries and API calls referencing summary continue to work.
Bug reports and crash reports are different things
Both end up in the same queue and they arrive from opposite directions.
A person writes a bug report because they noticed something wrong. A crash report is produced automatically when the software fails, and nobody decides to send it. Firebase Crashlytics is the standard example on mobile: once its SDK is added and initialised, crash reports are collected automatically for all users with no further instrumentation, and it groups crash, non-fatal and ANR events into issues based on stack trace frames, exception messages, error codes and other platform signals.
Automatic capture buys you volume and loses you intent. It also has quiet ceilings worth knowing if you rely on it as your record of what happened:
- 64 custom key-value pairs maximum, each up to 1 KB. Past that, additional pairs are not saved at all.
- Session logs are capped at 64 KB, and when the cap is reached older entries are removed starting from the oldest.
- Only the most recent eight recorded exceptions are stored per app session. If more occur, the earlier ones are lost.
- Crash data is retained about 90 days — stack traces, extracted minidump data and installation identifiers — after which removal begins.
None of that makes crash reporting less worth having; it is free to use and it catches failures nobody would have reported. But a crash report tells you the app stopped. It does not tell you the user had been trying to apply a discount code for four minutes, which is the sentence that usually explains the bug.
What is bug reporting failing at, in practice
Three failures account for most of it, and only one is about writing.
The fields people skip are the mechanical ones. Build, device, browser version, console state, the sequence of screens. A person is the worst available source for every one of them, and asking for them is asking someone to reconstruct from memory something a machine observed perfectly.
Reports get written at the worst moment. Someone hits a bug mid-task. Filing properly means abandoning what they were doing. Most people write something terse or file nothing — and the reports never written do not appear in any metric, which is why this failure stays invisible.
Longer forms make it worse. Every required field lowers the completion rate. Teams respond to bad reports by adding fields, which reduces the number of reports without improving them.
If you take one diagnostic from this page: count how many of your bugs get closed as cannot-reproduce. That number is the real measure of your software bug reporting, and it is unaffected by how good your template is.
Making the mechanical fields automatic
Since the fields that go missing are the ones a machine can observe, the durable fix is capture rather than discipline.
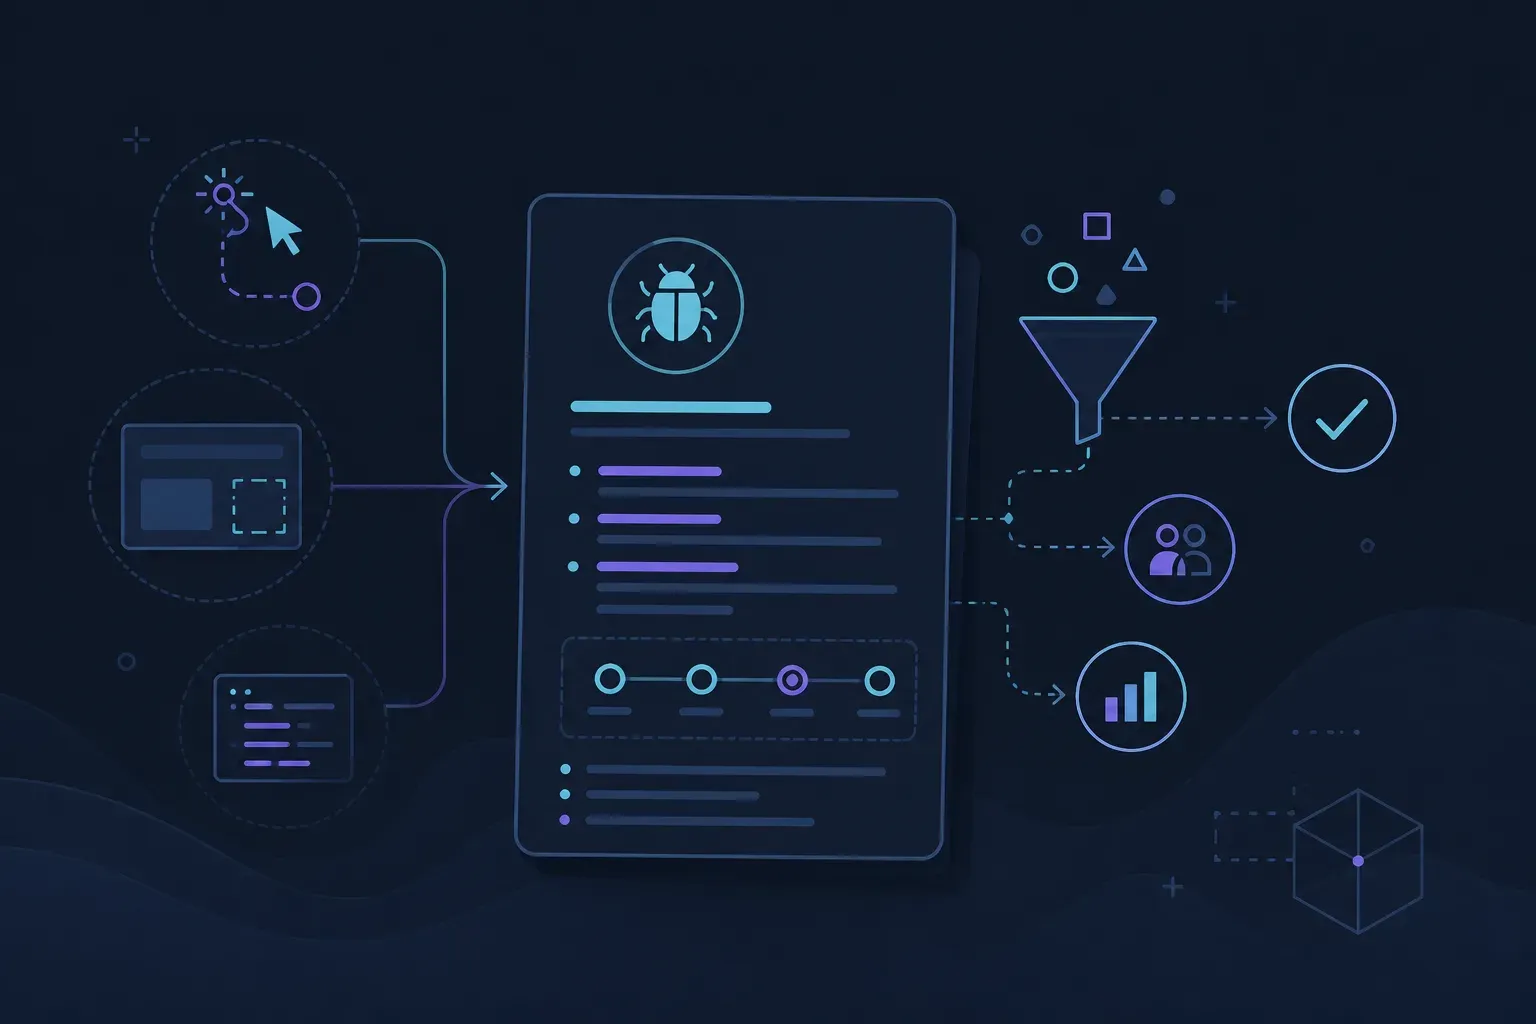
That is what TraceItX does. The reporter is inside the app being tested, so a person presses a bubble or a keyboard shortcut, annotates the screenshot, blurs anything sensitive, and sends. What arrives is one AI-ready envelope carrying the annotated screenshot, console and network state, device and app context, the build, and the trail of screens and actions leading to the report — up to 128 breadcrumbs on a single clock. Five of the seven fields above are filled before anyone types, and the steps to reproduce are captured whether or not the reporter thought to describe them.
Two fields still need a person: the title, and what they expected to happen. Those are the two worth asking for, and a form that asks for only those gets filled in.
What this does not do. There is no Jira, Linear or GitHub Issues app — reports arrive as signed webhooks and someone writes the receiver that maps them into your tracker. On the web it supports React only, with no framework-agnostic build. And it is not a crash-analytics platform: crash reporting is on by default and produces the same envelope a person would have filed, but there are no crash-free-rate dashboards, no alerting and no release health.
The short answer
A bug report exists to let someone else see the problem happen again. Judge yours by that and nothing else — not by length, not by how many fields are filled, and not by how many you receive.
If you want a practical next step rather than a definition: pick ten bugs closed as cannot-reproduce last quarter and read what they were missing. It is almost always the build, the environment, or the third step nobody wrote down.